RL Post-Training
01.2026 — presentppo from verifier reward on qwen2.5-0.5b
Post-training Qwen2.5-0.5B-Instruct on math, where the reward comes from a program that checks the answer rather than from a preference model. I built it to understand post-training by implementing it instead of reading about it.
Setup
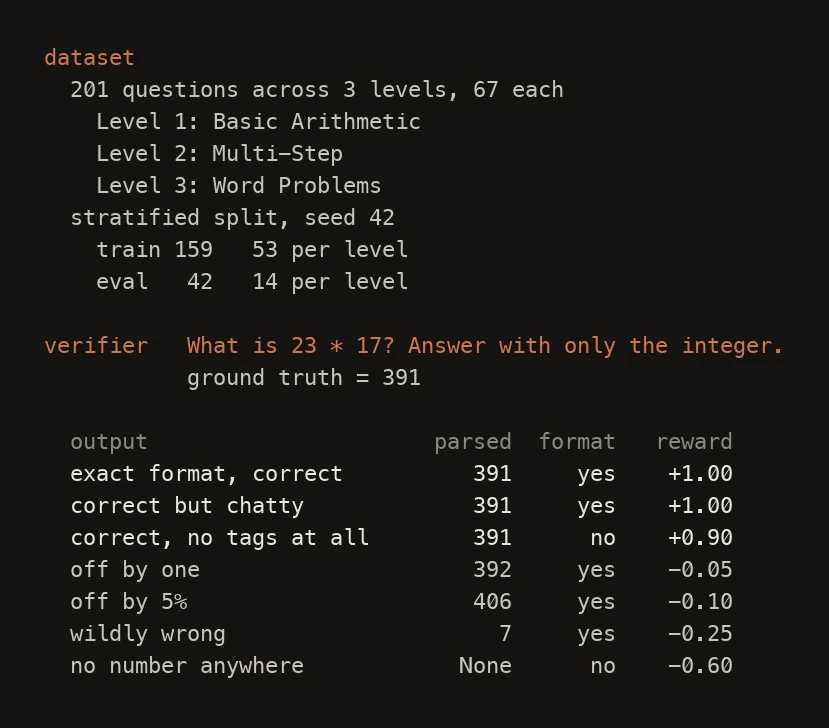
- — 201-question math benchmark with a deterministic 159 train / 42 eval split across three difficulty levels.
- — LoRA at r=8, alpha=16, targeting q_proj and v_proj, plus a custom value head for actor-critic training.
- — PPO with token-level log-probabilities, GAE advantage estimation, clipped policy updates, and KL regularization against a frozen reference model.
- — 50 epochs, 4 PPO update passes per batch, minibatches of 16, on RunPod GPUs.
The hard part was not the algorithm
PPO took a weekend. The verifier took much longer. A reward function that accepts a correct answer in the wrong format, or rejects a correct answer written a different way, teaches the model something extremely efficiently. Just not the thing you meant. Most of the real work went into the checker and the reward shaping around it.
What it ended up as: a full score only for a correct answer in the exact tagged format, a small deduction for a correct answer written loosely, and graded penalties for wrong answers scaled by relative error, so being off by one costs far less than being off by an order of magnitude. There is partial credit for correct intermediate results appearing in the reasoning, and a length penalty past 128 tokens.